Part 1 Done — You have mastered the basics
- ✓Variables & types — the values data is made of
- ✓Lists, strings & dictionaries — Python’s containers
- ✓Loops & if / else — repeat work, make decisions
- ✓Functions & errors — package it into robust tools
Every program so far ran on data you typed in by hand.
Real biology arrives as a file with thousands of rows — far too many to type. That's what Part 2 is for.
Part 2 — Python Meets Real Data
Handling big tables, running statistics, drawing figures, measuring images — Python is unusually good at all four, which is why it has become the language biologists reach for.
Does one neuron care what the whiskers felt?
arrays · numpy
Can a city feed its own bees?
tables · pandas
Which genes can a cancer cell not live without?
statistics · plots
How many cells are there, and what are they doing?
images as arrays
Four sessions, four real datasets, four real questions — and three of them come from labs in this building.
Today's Data — a Neuron Firing
We look at a trace of a neuron firing: its activity, measured 11 times a second for half an hour.
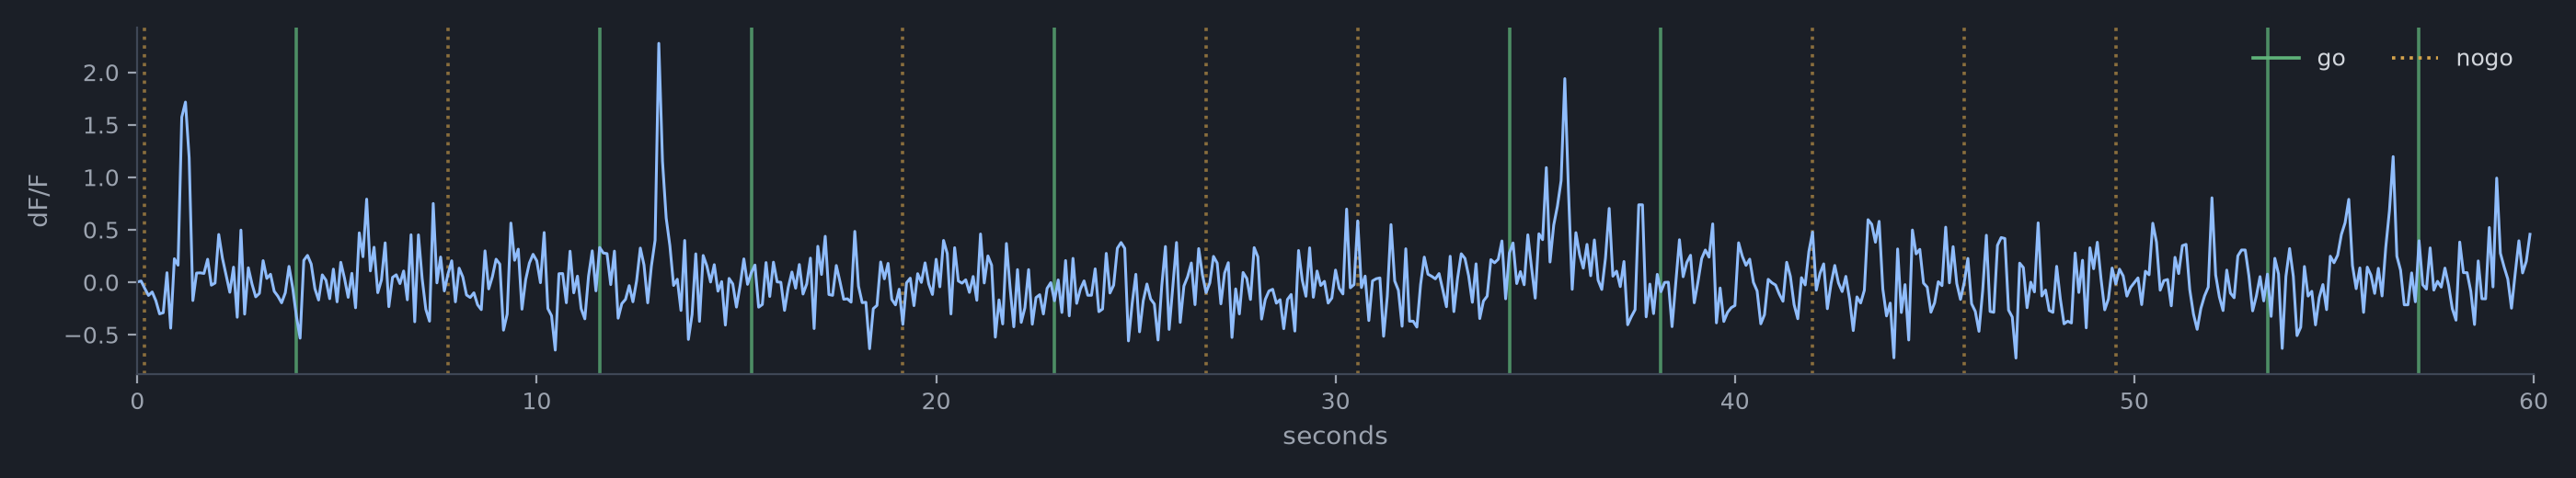
…from a single neuron, in a single session.
A list can't even subtract one number from all its values. We need better tools.
This Session — Tools for Real Data
From now on the data gets big, and the code it needs gets complex: processing huge arrays, handling tables, drawing plots, running statistics. Writing all of that from scratch would be impossible.
So programmers package their tools as classes — and you get to use theirs.
How Python bundles big tools into one thing you can use.
Import other people’s classes — first random.
The class built for thousands of numbers: arrays.
Use numpy to pull its answer out of the noise.
Understanding Object Oriented Programming 🧺
Steve Jobs' laundry story: two ways to get a dirty shirt clean in Tokyo.
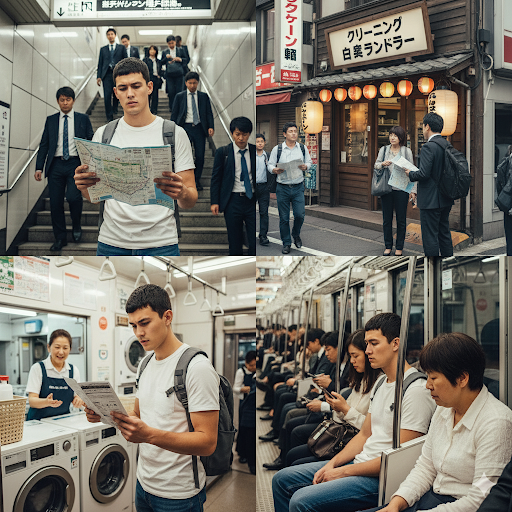
Find the laundromat, decode the machines, feed them coins — every step, in Japanese.
That is writing everything from scratch.
Understanding Object Oriented Programming 🧺
Steve Jobs' laundry story: two ways to get a dirty shirt clean in Tokyo.
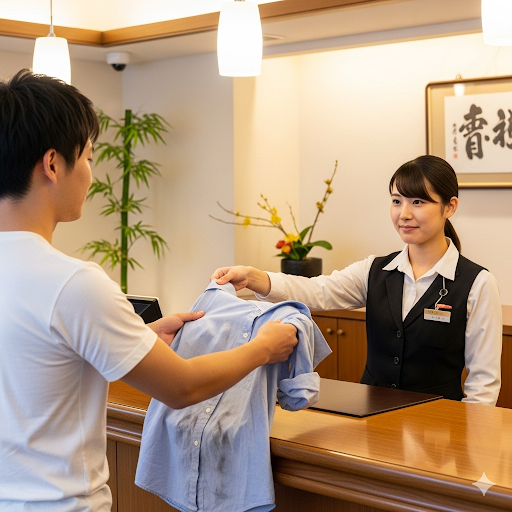
“Clean, please.” — and you never see the machine.
A class is that hotel: you talk to the reception, get a result back — and never see the machine.
Build the Simplest Object
Python bundles data and the functions that work on it into a class — the whole workflow, like the staff who wash and iron your shirt.
You never enter the laundry room. You use the reception: its attributes (what it holds — gene.sequence) and its methods (what it does for you — gene.gc_content()). Together they are the API, the application programming interface.
Data alone is just a container — a dictionary does that. The method makes it a hotel: your Lab 4 gc_content now travels with the data.
Run it — then build a second gene and ask it the same two things:
Borrow Other People's Classes
You get other people's classes with import — code someone already wrote and debugged. It comes from two places.
Ships with Python — nothing to install, just import.
- •random — chance, shuffling, sampling
- •math — sqrt, pi, logarithms
- •pathlib — files & folders (you met this in the lab)
- •datetime · csv — dates and simple tables
Written by the community, published on PyPI. You install them first — uv add pandas (Lab 2). In Colab, already done.
- •pandas — data tables
- •numpy — fast numbers & arrays
- •matplotlib — plots and figures
- •biopython — sequence tools
Either way, once it's imported you use its reception: import name → name.method()
Roll the Dice — random
random is in the standard library — one import and you can simulate chance: dice, coin flips, shuffling a deck, picking a sample.
random.randint(1, 6) — a whole number in a range · random.choice(list) — pick one · random.random() — a decimal 0–1
▶ Run it a few times. A different result every time. So… how does it decide? Hold that thought.
Run it, then run it again:
How Does random Actually Work?
When you call random.randint(1, 6), this is what runs underneath:
def genrand_uint32():
    y = mt[mti]
    y ^= (y >> 11)
    y ^= (y << 7)  & 0x9d2c5680
    y ^= (y << 15) & 0xefc60000
    y ^= (y >> 18)
    # …~600 more lines of the
# Mersenne Twister algorithmThat is the laundry room. random hides it behind one simple name — abstraction. You call it, you trust it, you move on.
What you do need: which methods it offers, what to pass in, what comes back.
📖 And you look it up — every package documents its API:docs.python.org/3/library/random.html
Use random's reception, one call at a time
You can't see the code behind the desk — like every package you import. The documentation is the whole interface.
import random

# random's reception (from the docs):
#   random.randint(a, b)   a whole number from a to b
#   random.choice(seq)     one item picked from seq
#   random.shuffle(x)      shuffle the list x in place
Step 1 — Call a method
Which line rolls a die?
import random
random.randintrandom.randint(1, 6)randint(1, 6)random.randint[1, 6]Step 2 — Pass an argument
Which line picks one random base from the list?
bases = ["A", "C", "G", "T"]
random.choice()bases.choice()random.choice(bases)random.choice("bases")Step 3 — Read the docs
The docs say shuffle(x) shuffles the list in place. What does this print?
bases = ["A", "C", "G", "T"]
result = random.shuffle(bases)
print(result)
A shuffled list, e.g. ['G', 'A', 'T', 'C']NoneAn error['A', 'C', 'G', 'T']Revision — Use random's Reception
Try this after the lecture. Three calls to the same reception — and a random DNA sequence at the end.
numpy — a class for numbers
A third-party package, and the one almost every scientific Python tool is built on. Its class is the array: thousands of numbers, handled as one.
Three Ways to Import
→ random.randint(1, 6)
The whole package. Every call starts with its full name.
→ np.array([1, 2, 3])
The same, with a short alias. Everyone writes np — you will see it in every example online.
→ array([1, 2, 3])
Only one name, used on its own. Short — but the reader no longer sees where it came from.
A List Can't Do Arithmetic
You have 21,238 readings and you want every one of them shifted, scaled or averaged. A list makes you write a loop. An array just does it.
You say what should happen to all the numbers, not how to visit them one at a time. One line instead of a loop — and far faster, as we'll see.
A Loop vs One numpy Call
The mean of 10 million numbers, done twice. Run it and watch the clock.
Python visits every value, one by one, 10 million times — checking what kind of thing each one is before it can add it.
An array holds only numbers, packed side by side. arr.mean() hands the whole block to fast compiled code in one go.
Same answer. Around a hundred times faster.
The Array's Reception
An array is an object, so it has a reception too:
.shape and .size tell you what it holds. .max(), .argmax() and .mean() do the work — on every number at once, whether there are 5 or 21,238.
Your class
gene.sequence
gene.gc_content()
A numpy array
readings.shape
readings.mean()
Attribute: no brackets. Method: brackets. Now let's use it on the neuron. →
What an Array Can Do
Every one of these is a method at the array's reception — and each works on 5 numbers or 5 million in one call. You don't learn them; you look them up.
- .sum()add them all
- .mean()the average
- .std()the spread
- .var()the variance
- .min() .max()smallest, largest
- .prod()multiply them all
- .cumsum()running total
- .argmax()where is the largest?
- .argmin()where is the smallest?
- .argsort()the order, by position
- .nonzero()where is it not 0?
- .any()is anything True?
- .all()is everything True?
- .searchsorted()where would it fit?
- .reshape()new rows × columns
- .flatten()back to one row
- .transpose()rows ↔ columns
- .squeeze()drop empty dimensions
- .swapaxes()swap two dimensions
- .diagonal()the diagonal
- .sort()sort in place
- .round()round every value
- .clip()cap values at a limit
- .astype()change the number type
- .repeat()repeat each value
- .copy()an independent copy
- .tolist()a plain Python list
- .item()one plain number
- .tofile()write to a file
- .take()pick by position
- .dot()matrix multiplication
…and about 20 more methods, plus hundreds of np functions. The full menu: numpy.org/doc → numpy.ndarray
Boolean Filtering — Keep What Passes
Compare an array with a number and you get one True or False per value — a mask. Put the mask in square brackets and only the True values are kept.
| readings | 0.1 | 0.5 | -0.2 | 0.8 | 0.3 | 0.9 |
|---|---|---|---|---|---|---|
| readings > 0.4 | False | True | False | True | False | True |
| readings[mask] | · | 0.5 | · | 0.8 | · | 0.9 |
With a list you would loop and test each value. With an array, one line asks all of them — and mask.sum() counts how many said True.
Where Is It? — argmax and np.where
Filtering tells you what passed. Often you need where — the positions.
| position | 0 | 1 | 2 | 3 | 4 | 5 |
|---|---|---|---|---|---|---|
| readings | 0.1 | 0.5 | -0.2 | 0.8 | 0.3 | 0.9 |
max() gives the value, 0.9. argmax() gives its position, 5.
np.where gives the positions of every True. It answers for each dimension, so it hands back a tuple — for a 1-D array, a tuple with one array in it. [0] takes that array out.
The numpy toolbox, one tool at a time
Six readings, three questions: filter them, find where they are, find the biggest.
import numpy as np

readings = np.array([0.1, 0.5, -0.2, 0.8, 0.3, 0.9])
#   position:          0    1     2    3    4    5
Step 1 — Filter
Which line keeps only the readings above 0.4?
readings = np.array([0.1, 0.5, -0.2, 0.8, 0.3, 0.9])
readings > 0.4readings[readings > 0.4][readings > 0.4]readings.filter(0.4)Step 2 — Where?
Which line gives the positions of the readings above 0.4, as a plain array?
readings = np.array([0.1, 0.5, -0.2, 0.8, 0.3, 0.9])
np.where(readings > 0.4)[0]np.where(readings > 0.4)readings[readings > 0.4](readings > 0.4).sum()Step 3 — Where is the biggest?
At which position is the largest reading? Which line tells you?
readings = np.array([0.1, 0.5, -0.2, 0.8, 0.3, 0.9])
readings.max()readings.index(0.9)readings.argmax()max(readings)Revision — The numpy Toolbox
Try this after the lecture. Filter, find where, find the biggest — the three tools the lab is built on.
One Neuron, Many Trials
A single trial tells you nothing. Two hundred and fifty of them, added up the right way, tell you what a cell is for.
The Experiment — Touching a Whisker 🐭
A mouse feels a short “word” of vibrations on its whiskers. The two words use the same vibrations in a different order — like dog and god.
- go — lick, and water arrives.
- nogo — don't lick; there is no water.
We record one neuron while the words play. Does it fire for go? Does it do the same for nogo — or can it tell them apart? You find out — from the numbers.
The Trace, With the Signals Marked
The trace from the start of the lecture — now with every go and nogo signal marked.
You can't. Neither can I — one trial is buried in noise. But the file holds 254 go trials, and averaging them is two lines of code. That is what today is for.
One row per reading: dff — activity above the neuron's resting level — plus a 0 or 1 for each event.
What Is Actually In the File
Every row is one moment in time. One column is the neuron; the rest say what was happening to the mouse.
frame     dff  go  nogo
   41  0.1512   0     0
   42 -0.0538   0     0
   43 -0.3234   1     0   <- go starts
   44 -0.5328   1     0
   45  0.2087   1     0
   46  0.2560   1     0
   47  0.1734   1     0
   48 -0.0613   1     0
   49 -0.1694   1     0
   50  0.0704   1     0
   51  0.0193   1     0   <- last go frame
   52 -0.1569   0     0
   53  0.1253   0     0
You can read the trial off the page: the go word starts at frame 43 and plays for 9 frames. That is one of 254. (The file has two more columns, reward and lick — we leave them out today.)
Your First Array
The file is a table. usecols=1 pulls out a single column — dff, the neuron — and hands it back as an array of 21,238 numbers.
The first 8 of 21,238 rows. Columns are counted from 0.
| frame0 | dff1 | go2 | nogo3 | |
|---|---|---|---|---|
| 0 | 0.0026 | 0 | 0 | |
| 1 | 0.0123 | 0 | 0 | |
| 2 | -0.0593 | 0 | 1 | |
| 3 | -0.1257 | 0 | 1 | |
| 4 | -0.0925 | 0 | 1 | |
| 5 | -0.1758 | 0 | 1 | |
| 6 | -0.3011 | 0 | 1 | |
| 7 | -0.2901 | 0 | 1 |
(21238,) — one number in the shape, so this is one-dimensional: a single row of values. Same reception as the five readings — only now it is the real recording.
Your Second Array — the go Signal
go and nogo are 0 or 1: is that signal playing at this frame? Here is one go trial, frame by frame. usecols=2 loads the go column — and every go signal is the same length.
| frame0 | dff1 | go2 | nogo3 | |
|---|---|---|---|---|
| 41 | 0.1512 | 0 | 0 | |
| 42 | -0.0538 | 0 | 0 | |
| 43 | -0.3234 | 1 | 0 | ← go word starts |
| 44 | -0.5328 | 1 | 0 | |
| 45 | 0.2087 | 1 | 0 | |
| 46 | 0.256 | 1 | 0 | |
| 47 | 0.1734 | 1 | 0 | |
| 48 | -0.0613 | 1 | 0 | |
| 49 | -0.1694 | 1 | 0 | |
| 50 | 0.0704 | 1 | 0 | |
| 51 | 0.0193 | 1 | 0 | ← last go frame |
| 52 | -0.1569 | 0 | 0 |
- go
- 1 while the go signal is playing — 9 frames in a row, 0 otherwise
- nogo
- the same for the nogo signal — also 9 frames in a row
Interrogate the array, no loops allowed
Two columns of one recording: the neuron's activity, and a 1 while the nogo signal is playing. Import numpy, then let the array do the counting.
# 1. ??? -- import numpy so that np works

F = "neuron_0588_20180828_5_lecture.csv"
dff  = np.loadtxt(F, delimiter=",", skiprows=1, usecols=1)
nogo = np.loadtxt(F, delimiter=",", skiprows=1, usecols=3)
Step 1 — Import numpy
Which line lets you write np.loadtxt(...)?
import numpyimport numpy as npfrom numpy import npimport npStep 2 — Frames or trials?
nogo is 1 for each of the 9 frames a nogo signal plays. How many nogo trials were there?
nogo = np.loadtxt(F, delimiter=",", skiprows=1, usecols=3)
len(nogo)nogo.sum()nogo.sum() / 9nogo.count(1) / 9Step 3 — The highest value
Which line gives the neuron's highest activity?
dff = np.loadtxt(F, delimiter=",", skiprows=1, usecols=1)
# dff.argmax() gives 11713: WHERE the highest value is, not what it is
dff.argmax()dff.max()dff.maxdff.highest()Revision — Interrogate the Array
Try this after the lecture. Import, count, find the peak. No loops — let the array do the work.
In the Lab — Does It Tell go From nogo?
One trial is lost in noise. Line up all 254, average them — then do the same for nogo and compare the two curves.
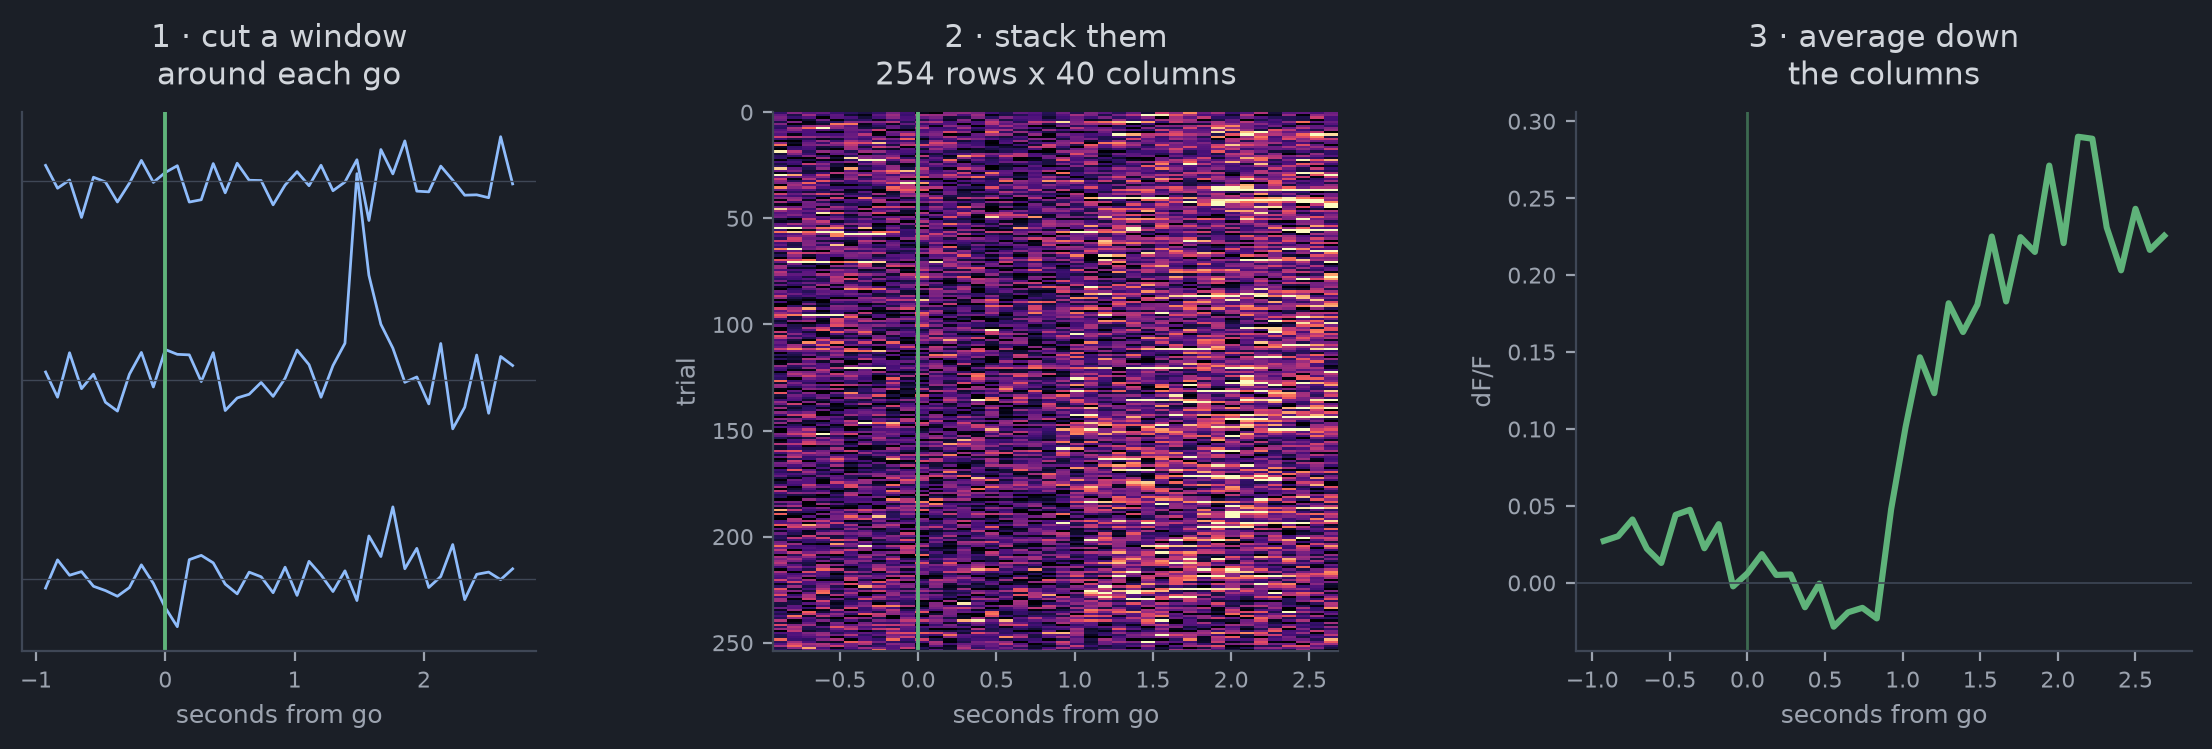
- 1
Find where each go signal starts
np.where
- 2
Cut the same window around each start
slicing
- 3
Stack the windows into a grid
np.array
- 4
Average down the columns
mean(axis=0)
Why that works: if the neuron responds to the signal, it responds at the same moment every time — but the noise is different every time. Average 254 trials and the noise cancels out. Whatever is left is real.
List or Array?
A list is a general-purpose container. An array is a block of numbers that does maths. Neither replaces the other.
Reach for a list when you are collecting things one at a time, or they aren't all numbers. Reach for an array the moment you want to do the same arithmetic to all of them.
What You Can Do Now
The real analysis: find every go trial, line them up, average — and find out whether this neuron tells go from nogo.
Put names on the columns and the grid becomes a DataFrame. Same idea, and suddenly you can ask it about bees.